Skip to content
Table of Contents

Table of Contents ​


Eigenvalues and Eigenvectors ​

Invariant Subspaces ​

Definition 5.1 - Invariant Subspace

Let T∈L(V) be a (linear) operator on vector space V. When we restrict T to a subspace U⊆V, we are not sure the corresponding vectors will still lie in U. If they do, we say that U is an invariant subspace under T. We call T|U is an operator on U.


Considering one special invariant subspace, that is, one-dimensional invariant subspace, which is spanned by only one vector v∈V. If this one-dimensional subspace is invariant under T, then the linear map T only depends on where the basis vector v is mapped, which leads to the concept of eigenvalues and eigenvectors:

Tv=λv

Eigenvalues ​

Definition 5.2 - Eigenvalue and Eigenvector

Let T∈L(V) be a (linear) operator on vector space V. A scalar λ∈F is called an eigenvalue of T if there exists a non-zero vector v∈V such that

Tv=λv.

The vector v is called an eigenvector corresponding to the eigenvalue λ.


Lemma 5.1 - Equivalence of Eigenvalue

Suppose V is a finite-dimensional vector space and T∈L(V), and λ∈F. The following statements are equivalent:

  1. λ is an eigenvalue of T.

  2. T−λI is not injective.

  3. T−λI is not surjective.

  4. det(T−λI)=0.


Proof

Regarding (1)⟺(2), by Tv=λv, we have (T−λIV)v=0. Since by linearity of vector space of L(V), T−λIV is also a operator on V, and its kernel is non-trivial as basis vector v is non-zero. Completing the proof of (1)⟺(2).

By the properties of invertible linear map of the same dimension

injectivity⟺surjectivity⟺bijectivity

, we have (2)⟺(3)⟺(4), completing the proof.


Lemma 5.2 - Linearly Independent Eigenvectors

Eigenvectors corresponding to distinct eigenvalues of a linear operator are linearly independent.


Proof

Suppose v1,v2,…,vk are eigenvectors corresponding to distinct eigenvalues λ1,λ2,…,λk of a linear operator T. We prove the statement by induction on k.

For k=1, the statement is trivial since a single non-zero vector is linearly independent.

Assume the statement holds for k−1 eigenvectors (i.e. if any linear combination of k−1 distinct eigenvectors equals zero, then all coefficients are zeros). Consider k eigenvectors v1,v2,…,vk corresponding to distinct eigenvalues λ1,λ2,…,λk. Suppose

a1v1+a2v2+⋯+akvk=0.

Applying T to both sides, we get

a1λ1v1+a2λ2v2+⋯+akλkvk=0.

Multiplying the first equation by λk and subtracting from the second equation, we obtain

a1(λ1−λk)v1+a2(λ2−λk)v2+⋯+ak−1(λk−1−λk)vk−1=0.

By the induction hypothesis, since λi≠λj for all i≠j, we have a1=a2=⋯=ak−1=0. Substituting back into the original equation, we get akvk=0, which implies ak=0 since vk≠0.

Hence, v1,v2,…,vk are linearly independent.


Lemma 5.3 - Maximum Number of Eigenvalues

A linear operator on an n-dimensional vector space has at most n distinct eigenvalues.


Proof

By lemma 5.2, eigenvectors corresponding to distinct eigenvalues are linearly independent. Since a linear operator on an n-dimensional vector space cannot have more than n linearly independent vectors, it follows that the number of distinct eigenvalues is at most n.


Polynomials Applies to Operators ​

Operators is more poppular than general linear maps, owe that the basis of domain and codomain are the same, thus invertibility is well-defined. Therefore, we can composite one operator many times, more in general we can apply any finite-degree polynomials to them directly.


Definition 5.3 - Polynomial Evaluation on Operator

Let T be a linear operator on a vector space V, and let p(x)=a0+a1x+⋯+amxm be a polynomial. The polynomial evaluation of p on T is defined as

p(T)=a0I+a1T+⋯+amTm,

where I is the identity operator on V. For simplicity, we call p(T) as polynomial operator on T.


Lemma 5.4 - Properties of Polynomial Operators

Due to the naive invertibility property of operators, the commutativity of operators with themselves ensures that polynomial evaluations on operators are well-defined and behave as expected. Suppose p,q∈P(F) are two polynomials, then we have

(a) p(T)+q(T)=(p+q)(T),(b) p(T)q(T)=(pq)(T),(c) p(T)q(T)=q(T)p(T).

Lemma 5.5 - Invariant of Null Space and Range of Polynomial Operators

Suppose T is a linear operator on a vector space V, and p(x) is a polynomial. Then the null space and range of p(T) are invariant under T, i.e.,

(a) T(null(p(T)))⊆null(p(T))(b) T(range(p(T)))⊆range(p(T)).
Proof

Regarding (a), it is suffices to show that ∀x∈T(null(p(T)))→x∈null(p(T)), which is equivalent with ∀x∈null(p(T))→T(x)∈null(p(T)).

By p(T)∈L(V), we have p(T)(x)=0. And T∈L(V), we have T(x)∈V, by the commutativity of polynomial operators, we have:

p(T)∘T(x)=(p(T)∘T)(x)=(T∘p(T))(x)=T(p(T)(x))=T(0)=0.

Thus T(x)∈null(p(T)).

Regarding (b), it is suffices to show that ∀y∈range(p(T))→T(y)∈range(p(T)).

Let y∈range(p(T)), then there exists x∈V such that y=p(T)(x). By the commutativity of polynomial operators, we have:

T(y)=T(p(T)(x))=(T∘p(T))(x)=(p(T)∘T)(x)=p(T)(T(x))∈range(p(T)).

Polynomial Operators and Eigenvalues

What is the relationship between polynomial operators and eigenvalues?

The Minimal Polynomial ​

Lemma 5.6 - Existence of Eigenvalues

Every operator on a finite-dimensional vector space over an algebraically closed field has at least one eigenvalue.

Proof

We will show the proof on the perspective of the characteristic polynomial of the operator. Since the field is algebraically closed, the characteristic polynomial has at least one root, which corresponds to an eigenvalue of the operator.

Suppose V is a finite-dimensional complex vector space of dimension n, and let T be a linear operator on V. Choose a non-zero vector v∈V. Then

v,Tv,T2v,…,Tnv,

is a list of dependent vectors in V since V has dimension n. Thus, there exist scalars a0,a1,…,an, not all zero, such that

a0v+a1Tv+a2T2v+⋯+anTnv=p(T)(v)=0.

where p(x) is a non-constant polynomial of smallest degree such that p(T)(v)=0. "algebraically closed" ensures the characteristic polynomial has at least one root in the field λ∈F such that p(x)=(x−λ)q(x)=0, "Smallest degee" ensures that the quotient polynomial q(λ)≠0, and therefore we have:

p(T)(v)=((T−λI)q(T))(v)=(T−λI)(q(T)(v))=0.

concequently, T−λI=0 which implies that v is an eigenvector of T corresponding to the eigenvalue λ.


Definition 5.4 - Minimal Polynomial

The minimal polynomial of a linear operator T on a finite-dimensional vector space V is the unique monic polynomial p∈P(F) of smallest degree such that p(T)=0. Furthermore, deg⁡p≤dim⁡V.


Algebraically Closed Fields

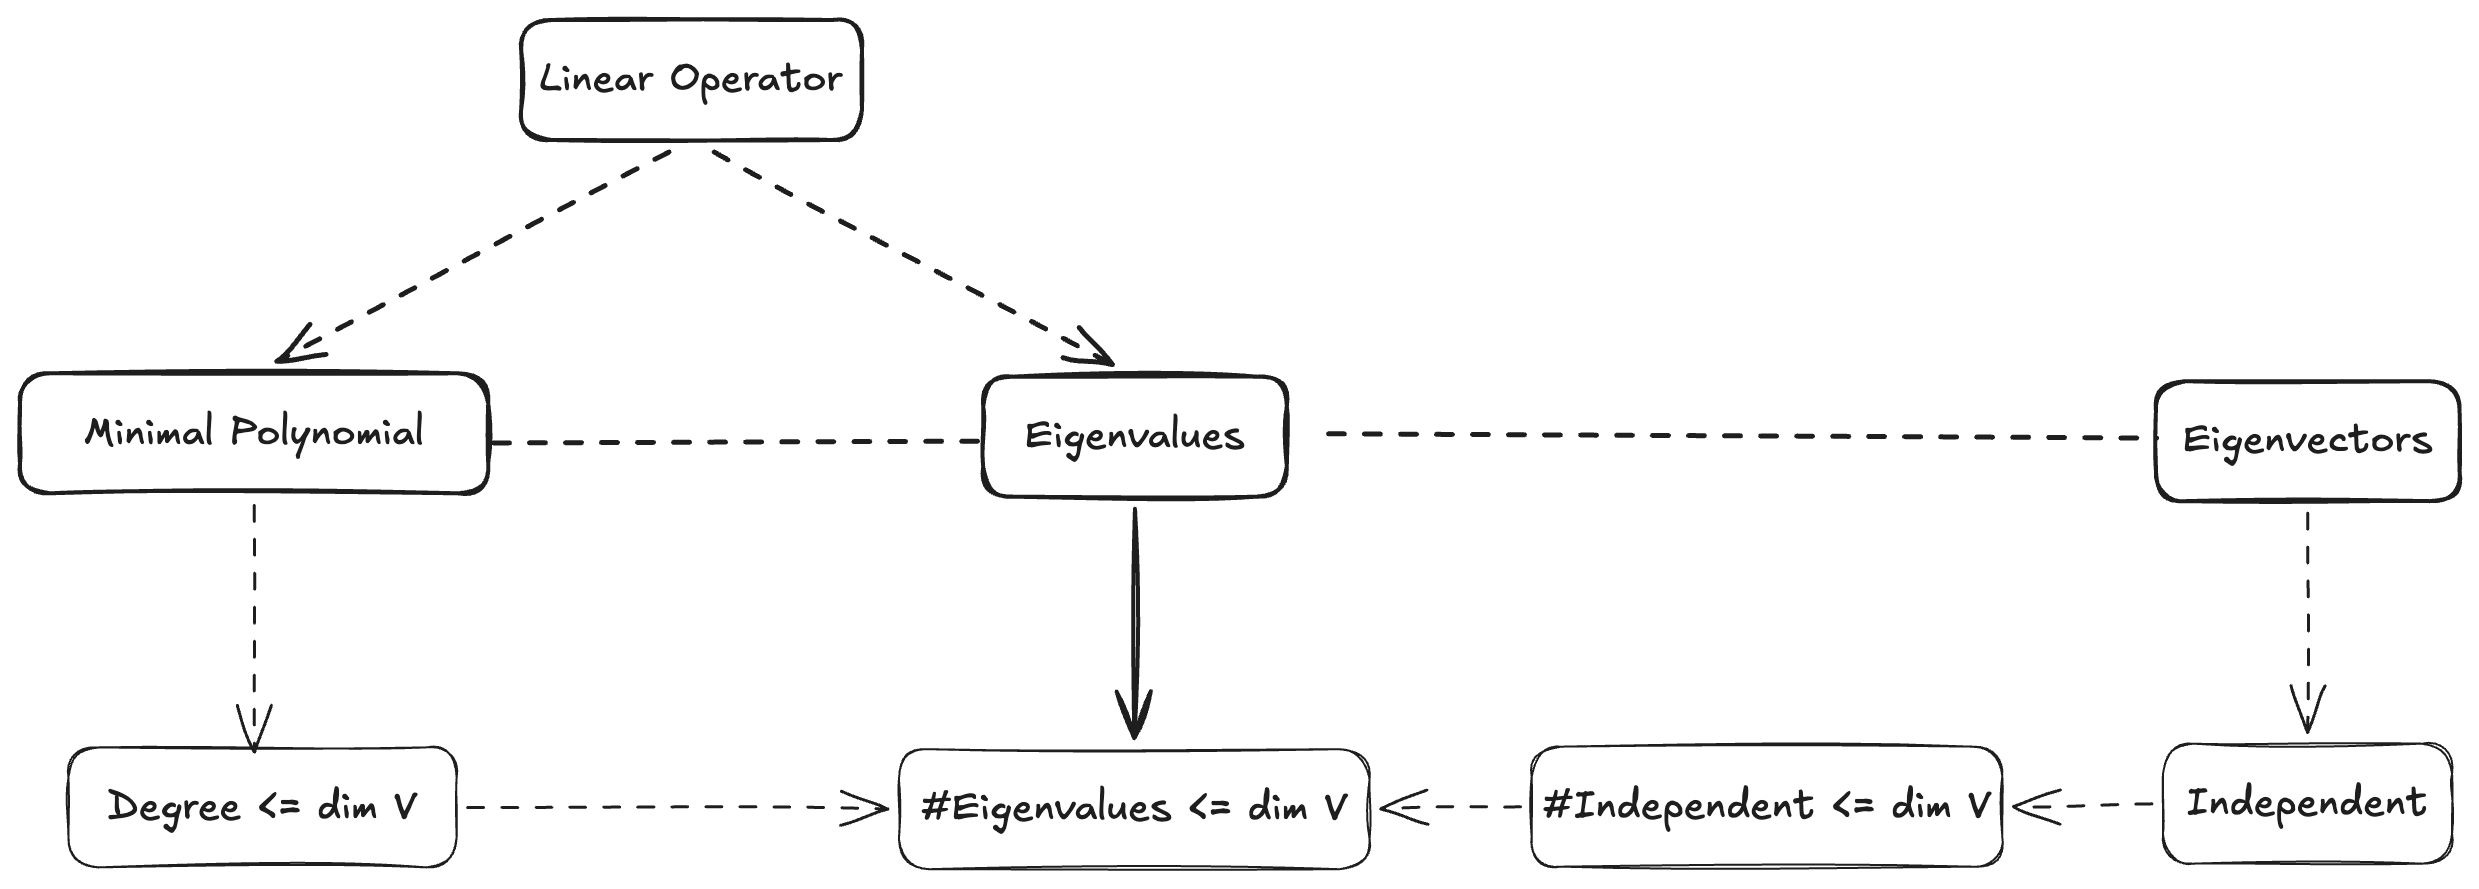
What is the relationship between minimal polynomial and eigenvalues? Given a linear operator T, the minimal polynomial of it always exists and be unique. But by lemma 5.6, the existence of eigenvalues still depends on the field being algebraically closed. By comparison, R is not algebraically closed, while C is.


Lemma 5.7 - Relationship Between Minimal Polynomial and Eigenvalues

Suppose V is finite-dimensional and T∈L(V).

  • (a) If the field F which vector space is defined over is not algebraically closed, for example R, then the zeros of the minimal polynomial of T are the eigenvalues of T in F, if any exist.
  • (b) If the field F is algebraically closed, for example C, then there are at least one zero of the minimal polynomial of T in F, which corresponds to an eigenvalue of T.

This lemma also implies that the number of distinct eigenvalues of T in F is at most the degree of the minimal polynomial of T, which in turn is at most dim⁡V. For now, we have two ways to show that the number of distinct eigenvalues is bounded by the dimension of the vector space. One is using the minimal polynomial, and the other is using eigenvectors directly.
bound-for-eigenvalues


Lemma 5.8 - Invertible of Linear Operators

Suppose V is finite-dimensional and T∈L(V). Then T is invertible if and only if 0 is not an eigenvalue of T, which is equivalent to the minimal polynomial of T not having 0 as a root.

Proof

T is not invertible, implying not injective, which means

\existu,v∈V,T(u)=T(v)→u≠v

Thus T(u)−T(v)=T(u−v)=0=0⋅(u−v), which shows that 0 is an eigenvalue of T with eigenvector u−v≠0. By lemma 5.7, 0 is a root of the minimal polynomial of T, implying that the constant term of the minimal polynomial is 0.


Eigenvalues on Odd-Dimensional Real Vector Spaces ​

By lemma 5.7, we have concluded that not every linear operator on a real vector space has eigenvalues. But in some special circumstances, such as when the vector space is odd-dimensional, we can guarantee the existence of eigenvalues.


Upper-Triangular Matrices ​

For example,

(a11a12⋯a1n0a22⋯a2n⋮⋮⋱⋮00⋯ann)

is an upper-triangular matrix.


Diagonal matrix is a special case of an upper-triangular matrix where all the entries above and below the main diagonal are zero.

Before we dive into diagonal matrix of linear operator, we first need to understand upper-triangular matrices, as they provide a stepping stone towards diagonalization.


Lemma 5.9 - Conditions for Upper-Triangular Matrix

Suppose T∈L(V) is a linear operator on a finite-dimensional vector space V. Then the following conditions are equivalent:

  • (a) The matrix of T with respect to some basis v1,...,vn of V is upper-triangular.
  • (b) span(v1,...,vk) is invariant under T for each k=1,...,n.
Proof

Since M(T) is an upper-triangular matrix with respect to the basis v1,...,vn, by the definition of linear map matrix, we have T(vj)∈span(v1,...,vj)⊆span(v1,...,vk) for each j=1,...,k, so

T(c1v1+⋯+ckvk)=c1T(v1)+⋯+ckT(vk)∈span(v1,...,vk)

. Completing the proof of the equivalence between (a) and (b).


Lemma 5.10 - Linear Operator Equation

Suppose T∈L(V) is a linear operator on a finite-dimensional vector space V, and it has an upper-triangular matrix with diagonal entries λ1,...,λn. Then

(T−λ1I)(T−λ2I)⋯(T−λnI)=0

Lemma 5.11 - Determination of Eigenvalues from Upper-Triangular Matrix

Suppose T∈L(V) is a linear operator on a finite-dimensional vector space V, and it has an upper-triangular matrix with diagonal entries λ1,...,λn. Then the eigenvalues of T are precisely λ1,...,λn.


Not every linear operator has an upper-triangular matrix representation with respect to some basis. Those that do are called triangularizable operators.

Lemma 5.12 - Condition for Having Upper-Triangular Matrix

Suppose T∈L(V) is a linear operator on a finite-dimensional vector space V. Then T has an upper-triangular matrix with respect to some basis of V if and only if the minimal polynomial of T equals

(x−λ1)⋯(x−λm)

for some scalars λ1,...,λm∈F, where m≤n. More specially, if the field F is algebraically closed, then every linear operator on a finite-dimensional vector space over F has an upper-triangular matrix with respect to some basis.


Diagonalizable Operators ​

Definition 5.5 - Eigenspace

Suppose T∈L(V) is a linear operator on a finite-dimensional vector space V, and λ is an eigenvalue of T. The eigenspace corresponding to λ is defined as

E(λ,T)=null(T−λI)={v∈V:T(v)=λv}.

We see that each eigenspace is a subspace of V, meaning it is closed under vector addition and scalar multiplication, i.e.,

v1,v2∈E(λ,T),α,β∈F⟹αv1+βv2∈E(λ,T).

WARNING

Each eigenvalue corresponds to a eigenspace, so what is the relationship between these eigenspaces?


Lemma 5.13 - Sum of Eigenspaces

Suppose T∈L(V) is a linear operator on a finite-dimensional vector space V, and λ1,...,λm are distinct eigenvalues of T. Then the sum of the corresponding eigenspaces is direct, i.e.,

E(λ1,T)⊕⋯⊕E(λm,T)⊆V.

Furthermore, if V is finite-dimensional, then the sum of the eigenspaces equals V, i.e.,

dim⁡E(λ1,T)⊕⋯⊕E(λm,T)≤dim⁡V.
Proof

(a) In order to show the direct-sum, it is suffices to show that : the only way to write the zero vector as a sum of vectors from each eigenspace is by taking each vector to be zero, i.e.,

0=v1+⋯+vm,

where vi∈E(λi,T) for each i=1,...,m. We need to show that each vi=0.

Because each eigenvector vi corresponds to a distinct eigenvalue λi, they are linearly independent. Therefore, vi=0 for each i=1,...,m.

(b) Since the sum of the eigenspaces is direct, then we have

dim⁡(E(λ1,T)⊕⋯⊕E(λm,T))=dim⁡E(λ1,T)+⋯+dim⁡E(λm,T).

and E(λ1,T)⊕⋯⊕E(λm,T)⊆V implies

dim⁡(E(λ1,T)⊕⋯⊕E(λm,T))≤dim⁡V.

Completing the proof.


Lemma 5.14 - Euqivalent Conditions for Diagonalizability

Suppose T∈L(V) is a linear operator on a finite-dimensional vector space V. Let λ1,...,λm be the distinct eigenvalues of T. Then the following are equivalent:

  1. T is diagonalizable.

  2. V has a basis consisting of eigenvectors of T.

  3. The sum of the eigenspaces corresponding to λ1,...,λm equals V, i.e.,

    E(λ1,T)⊕⋯⊕E(λm,T)=V.
  4. dim⁡E(λ1,T)+⋯+dim⁡E(λm,T)=dim⁡V.


Proof

Suppose the diagonal matrix of linear operator T with respect to some basis {v1,...,vn} of V is

diag(λ1,...,λn),

where λj are the eigenvalues corresponding to the basis vectors vj. Note that m≤n implies that it is possible multiple eigenvectors share the same eigenvalue.


For (1)⟺(2), recalling the upper-triangular matrix of linear operator, Tvj∈span(v1,...,vj) for each j≤n, where {v1,...,vn} is a basis of V. Diagonal matrix is more strict than upper-triangular matrix, as it only has diagonal entries. By the definition of linear map matrix, we have Tvj=λjvj for each j, which shows that each basis vector vj is an eigenvector corresponding to eigenvalue λj. Hence, (1)⟺(2).

For (2)⟺(3), E(λj,T) is a subspace of V for each j=1,...,m, thus E(λ1,T)⊕⋯⊕E(λm,T) is also a subspace of V. So in order to show V=E(λ1,T)⊕⋯⊕E(λm,T), it suffices to show that V⊆E(λ1,T)⊕⋯⊕E(λm,T).

Since eigenvectors v1,...,vn form a basis of V, then

v=c1v1+⋯+cnvn,

Since vj∈E(λj,T) for each j, we have

v=c1v1+⋯+cnvn∈E(λ1,T)⊕⋯⊕E(λm,T),

which shows that the sum of the eigenspaces equals V. Hence, (2)⟺(3).

For (3)⟺(4),

dim⁡(E(λ1,T)⊕⋯⊕E(λm,T))=dim⁡E(λ1,T)+⋯+dim⁡E(λm,T).

and E(λ1,T)⊕⋯⊕E(λm,T)=V implies

dim⁡(E(λ1,T)⊕⋯⊕E(λm,T))=dim⁡V.

Lemma 5.15 - Enough Eigenvalues for Diagonalizability

Suppose T∈L(V) is a linear operator on an n-dimensional vector space V, and it has dim⁡V distinct eigenvalues. Then T is diagonalizable.


Proof

By lemma 5.14, we observe that : n distinct eigenvectors forming a basis of V does not guarantee that they come from n distinct eigenvalues, implying that some eigenvalues has mutiplicity than one.

This lemma is a special case of lemma 5.14, where the number of distinct eigenvalues equals the dimension of the vector space. We just omit the proof here.


Lemma 5.16 - Sufficient and Necessary Conditions for Diagonalizability

Suppose T∈L(V) is a linear operator on an n-dimensional vector space V. Then T is diagonalizable if and only if the minimal polynomial of T equals

∏i=1m(x−λi),

where λ1,...,λm are the distinct eigenvalues of T.

Criterias for Diagonalizability

For now, we have four criterias for diagonalizability of a linear operator, where three of them come from lemma 5.14 and the fourth one comes from lemma 5.15. The difference is that :

  1. lemma 5.15 is a sufficient condition for diagonalizability, but not necessary condition, which means there are other ways to achieve diagonalizability without having dim⁡V distinct eigenvalues, for example the three conditions (2), (3), and (4) in lemma 5.14.
  2. lemma 5.16 provides a necessary and sufficient condition for diagonalizability, which means it characterizes all diagonalizable operators through their minimal polynomials.

Lemma 5.17 - Restriction of Diagonalizable Operators

Suppose T∈L(V) is a diagonalizable linear operator on an n-dimensional vector space V, and W is a T-invariant subspace of V. Then the restriction of T to W, denoted by T|W, is also diagonalizable.


IMPORTANT

In this section, we have learned that a linear operator is diagonalizable only when using some special basis consisting of its eigenvectors. The choice of such a basis is crucial for representing the operator in a diagonal form.

Commuting Operators ​

If two operators are commuting, i.e., AB=BA, then they are said to commute with each other.

Lemma 5.18 - Commuting Operators and Commuting Matrices

Suppose S and T are two linear operators on a finite-dimensional vector space V, and v1,...,vn is a basis of V. Then S and T commute if and only if M(S,{v1,...,vn}) and M(T,{v1,...,vn}) commute.


Lemma 5.19 - Eigenspace is invariant under commuting operator

Suppose S,T∈L(V) are two commuting linear operators on a finite-dimensional vector space V and λ∈F. Then E(λ,S), the eigenspace of S corresponding to λ, is invariant under T.

Proof

To show the invariance of E(λ,S) under T, it is sufficient to show :

∀v∈E(λ,S)→T(v)∈E(λ,S)⟺S(T(v))=λ⋅T(v)

Since S,T commute, ST=TS, so we have S(T(v))=T(S(v))=T(λv)=λT(v), which shows that T(v)∈E(λ,S).


Lemma 5.20 - Simultaneous Diagonalizability of Commuting Operators

Two diagonalizable linear operators on a finite-dimensional vector space V commute if and only if they are simultaneously diagonalizable, i.e., there exists a basis of V consisting of eigenvectors common to both operators.


Inner Product Spaces ​

So far, we have discussed

  • linear structure of vector spaces,
  • linear maps (operators) on them,
  • and properties of these operators.

Actually, there are also some geometric features (for example, lengths and angles) for vector spaces, which can be captured using the concept of an inner product. Similarly, we will then discuss linear operators on inner product spaces and their properties.

Inner Products and Norms ​

Definition 6.1 - Euclidean (Inner Product) Space

An inner product on a vector space V over the field F (where F is typically R or C) is a function ⟨⋅,⋅⟩:V×V→F that satisfies the following properties for all u,v,w∈V and all α∈F:

  1. Conjugate Symmetry: ⟨u,v⟩=⟨v,u⟩―
  2. Linearity in the First Argument: ⟨αu+v,w⟩=α⟨u,w⟩+⟨v,w⟩
  3. Positive-Definiteness: ⟨v,v⟩≥0 with equality if and only if v=0

A vector space V equipped with an inner product ⟨⋅,⋅⟩ is called an inner product space or Euclidean space.


Definition 6.2 - Norm Induced by Inner Product

For a vector v∈V, the norm induced by the inner product is defined as

∥v∥=⟨v,v⟩.

This norm satisfies the usual properties of a norm, including positivity, homogeneity, and the triangle inequality, that is,

∥v∥≥0,∥v∥=0⟺v=0,∥αv∥=|α|⋅∥v∥,∥u+v∥≤∥u∥+∥v∥.

Definition 6.3 - Orthogonality

Two vectors u,v∈V are said to be orthogonal if their inner product is zero, i.e.,

⟨u,v⟩=0.

Lemma 6.1 - Pythagorean Theorem for Inner Product Spaces

If u,v∈V are orthogonal, then

∥u+v∥2=∥u∥2+∥v∥2.
Proof

If u and v are orthogonal, then ⟨u,v⟩=⟨v,u⟩―=0 implies ⟨v,u⟩=0, thus

∥u+v∥2=⟨u+v,u+v⟩=⟨u,u⟩+⟨u,v⟩+⟨v,u⟩+⟨v,v⟩=∥u∥2+∥v∥2.

Lemma 6.4 - Cauchy-Schwarz Inequality

For all vectors u,v∈V, the Cauchy-Schwarz inequality states that

|⟨u,v⟩|≤∥u∥⋅∥v∥.

Equality holds if and only if u and v are linearly dependent.


Lemma 6.5 - Triangle Inequality

For all vectors u,v∈V, the triangle inequality states that

∥u+v∥≤∥u∥+∥v∥.

Equality holds if and only if u and v are linearly dependent.


Lemma 6.6 - Parallelogram Law

For all vectors u,v∈V, the parallelogram law states that

∥u+v∥2+∥u−v∥2=2∥u∥2+2∥v∥2.

Orthonormal Bases ​

Definition 6.4 - Orthonormal

An orthonormal set of vectors in an inner product space V is a set of vectors that are all unit vectors (norm equal to 1) and mutually orthogonal. Formally, a set {e1,e2,…,en}⊆V is orthonormal if

⟨ei,ej⟩=δij,for all i,j=1,2,…,n,

where δij is the Kronecker delta, which is 1 if i=j and 0 otherwise.


We have two properties about orthonormal list of vectors :

  1. ∥a1e1+...+anen∥2=|a1|2+...+|an|2 for any scalars a1,…,an.
  2. Every orthonormal list of vectors is linearly independent.

Lemma 6.7 - Bessel's Inequality

Let {e1,e2,…,en} be an orthonormal set of vectors in an inner product space V. For any vector v∈V, Bessel's inequality states that

∑i=1n|⟨v,ei⟩|2≤∥v∥2.

NOTE

⟨v,ei⟩ represents the inner product of the vector v with the orthonormal basis vector ei, which can be directly interpreted as the scalar projection (or coefficient) of v onto ei.


Definition 6.5 - Orthonormal Basis

An orthonormal basis of an inner product space V is an orthonormal set of vectors that spans the entire space V. Formally, a set {e1,e2,…,en}⊆V is an orthonormal basis if it is orthonormal and every vector v∈V can be expressed as a linear combination of the basis vectors:

v=∑i=1n⟨v,ei⟩ei.

NOTE

Orthonormal basis is a special kind of basis where all the basis vectors are orthonormal, meaning they are all unit vectors and mutually orthogonal. But how to find such a basis in practice? One common method is the Gram-Schmidt process, which takes a linearly independent set of vectors and constructs an orthonormal basis from them.


Definition 6.6 - Orthogonal Decomposition

Suppose u,v∈V, with v≠0. Set

w=⟨u,v⟩∥v∥2v,

then u can be decomposed as

u=w+(u−w),

where w is parallel to v and u−w is orthogonal to v.

NOTE

It implies that any vector u can be decomposed into a component parallel to another vector v and a component orthogonal to v.


Lemma 6.8 - Gram-Schmidt Procedure

Suppose v1,...,vm is a linearly independent set of vectors in an inner product space V. The Gram-Schmidt procedure constructs an orthonormal set of vectors e1,...,em as follows:

  1. Let f1=v1
  2. For k=2,...,m inductively definefk=vk−∑i=1k−1⟨vk,fi⟩∥fi∥2fi,
  3. For each k=1,...,m, letek=fk∥fk∥.Then e1,...,em is an orthonormal set of vectors that spans the same subspace as {v1,...,vm}, i.e.,span{e1,...,em}=span{v1,...,vm}.

NOTE

The general ideal is that, firstly by definition 6.6, we construct a set of orthonormal vectors f1,...,fm from the original linearly independent set v1,...,vm. Secondly, normalize them to obtain the orthonormal set e1,...,em.


Lemma 6.9 - Orthonormal List to Orthonormal Basis

The length of any orthonormal list is not guarrenteed to be dim⁡V, but it can always be extended to form an orthonormal basis of V by applying the Gram-Schmidt procedure to additional linearly independent vectors until the basis is complete.


Lemma 6.10 - Upper-triangular Matrix with Respect to Orthonormal Basis

By lemma 5.12, every linear operator on a finite-dimensional inner product space has an upper-triangular matrix with respect to some basis. It does not specify which basis, but in fact, it can be chosen to be an orthonormal basis.

Suppose T∈L(V), where V is a finite-dimensional inner product space. Then T has an upper-triangular matrix with respect to some orthonormal basis of V if and only if the minimal polynomial of T splits into linear factors over the field F. That is,

minimal polynomial of T=∏i=1m(x−λi),λi∈F.

Definition 6.7 - Orthogonal Complement

Given U is a subset of V, the orthogonal complement of U, denoted by U⊥, is defined as

U⊥={v∈V∣⟨v,u⟩=0 for all u∈U}.

Orthogonal complement has the following properties:

  1. U⊥ is a subspace of V.
  2. {0}⊥=V
  3. V⊥={0}.
  4. U∩U⊥={0}.
  5. if G⊆H, then H⊥⊆G⊥.

WARNING

We did not specify that U is a subspace in the definition of orthogonal complement. Therefore, U⊥ is always a subspace of V regardless of whether U itself is a subspace.

Lemma 6.11 - Direct-sum Decomposition with Orthogonal Complement

Suppose U is a subspace of a finite-dimensional inner product space V. Then

V=U⊕U⊥.

In this case, we have :

(a) dim⁡V=dim⁡U+dim⁡U⊥(b) U=(U⊥)⊥

Definition 6.8 - Orthogonal Projection

Suppose U is a finite-dimensional subspace of a finite-dimensional inner product space V. The orthogonal projection of V onto U is the linear operator PU∈L(V) defined as follows : For each v∈V, write v=u+w, where u∈U and w∈U⊥. Then

PU(v)=u.

NOTE

We know that, given a vector v∈V, there are many ways to decompose it v=u+w, where u,w∈V. However there is only one way to decompose it such that u∈U and w∈U⊥. This ensures that the orthogonal projection PU(v) is well-defined. The linear operator is also used to extract the component of v that lies in U.

The properties of orthogonal projection include:

  1. PU∈L(V).
  2. PUu=u for all u∈U.
  3. PUw=0 for all w∈U⊥.
  4. range(PU)=U.
  5. null(PU)=U⊥.
  6. v−PU(v)∈U⊥ for all v∈V.
  7. PU2=PU (idempotent property).
  8. ∥PU(v)∥≤∥v∥ for all v∈V.
  9. if e1,...,em is an orthonormal basis of U, then for all v∈V,
PU(v)=∑i=1m⟨v,ei⟩ei.

Lemma 6.12 - Minimizing Distance to a Subspace

Suppose U is a finite-dimensional subspace of a finite-dimensional inner product space V. For any v∈V, the distance from v to U is minimized by the orthogonal projection of v onto U. In other words,

∥v−PU(v)∥=minu∈U∥v−u∥.

Operators on Inner Product Spaces ​

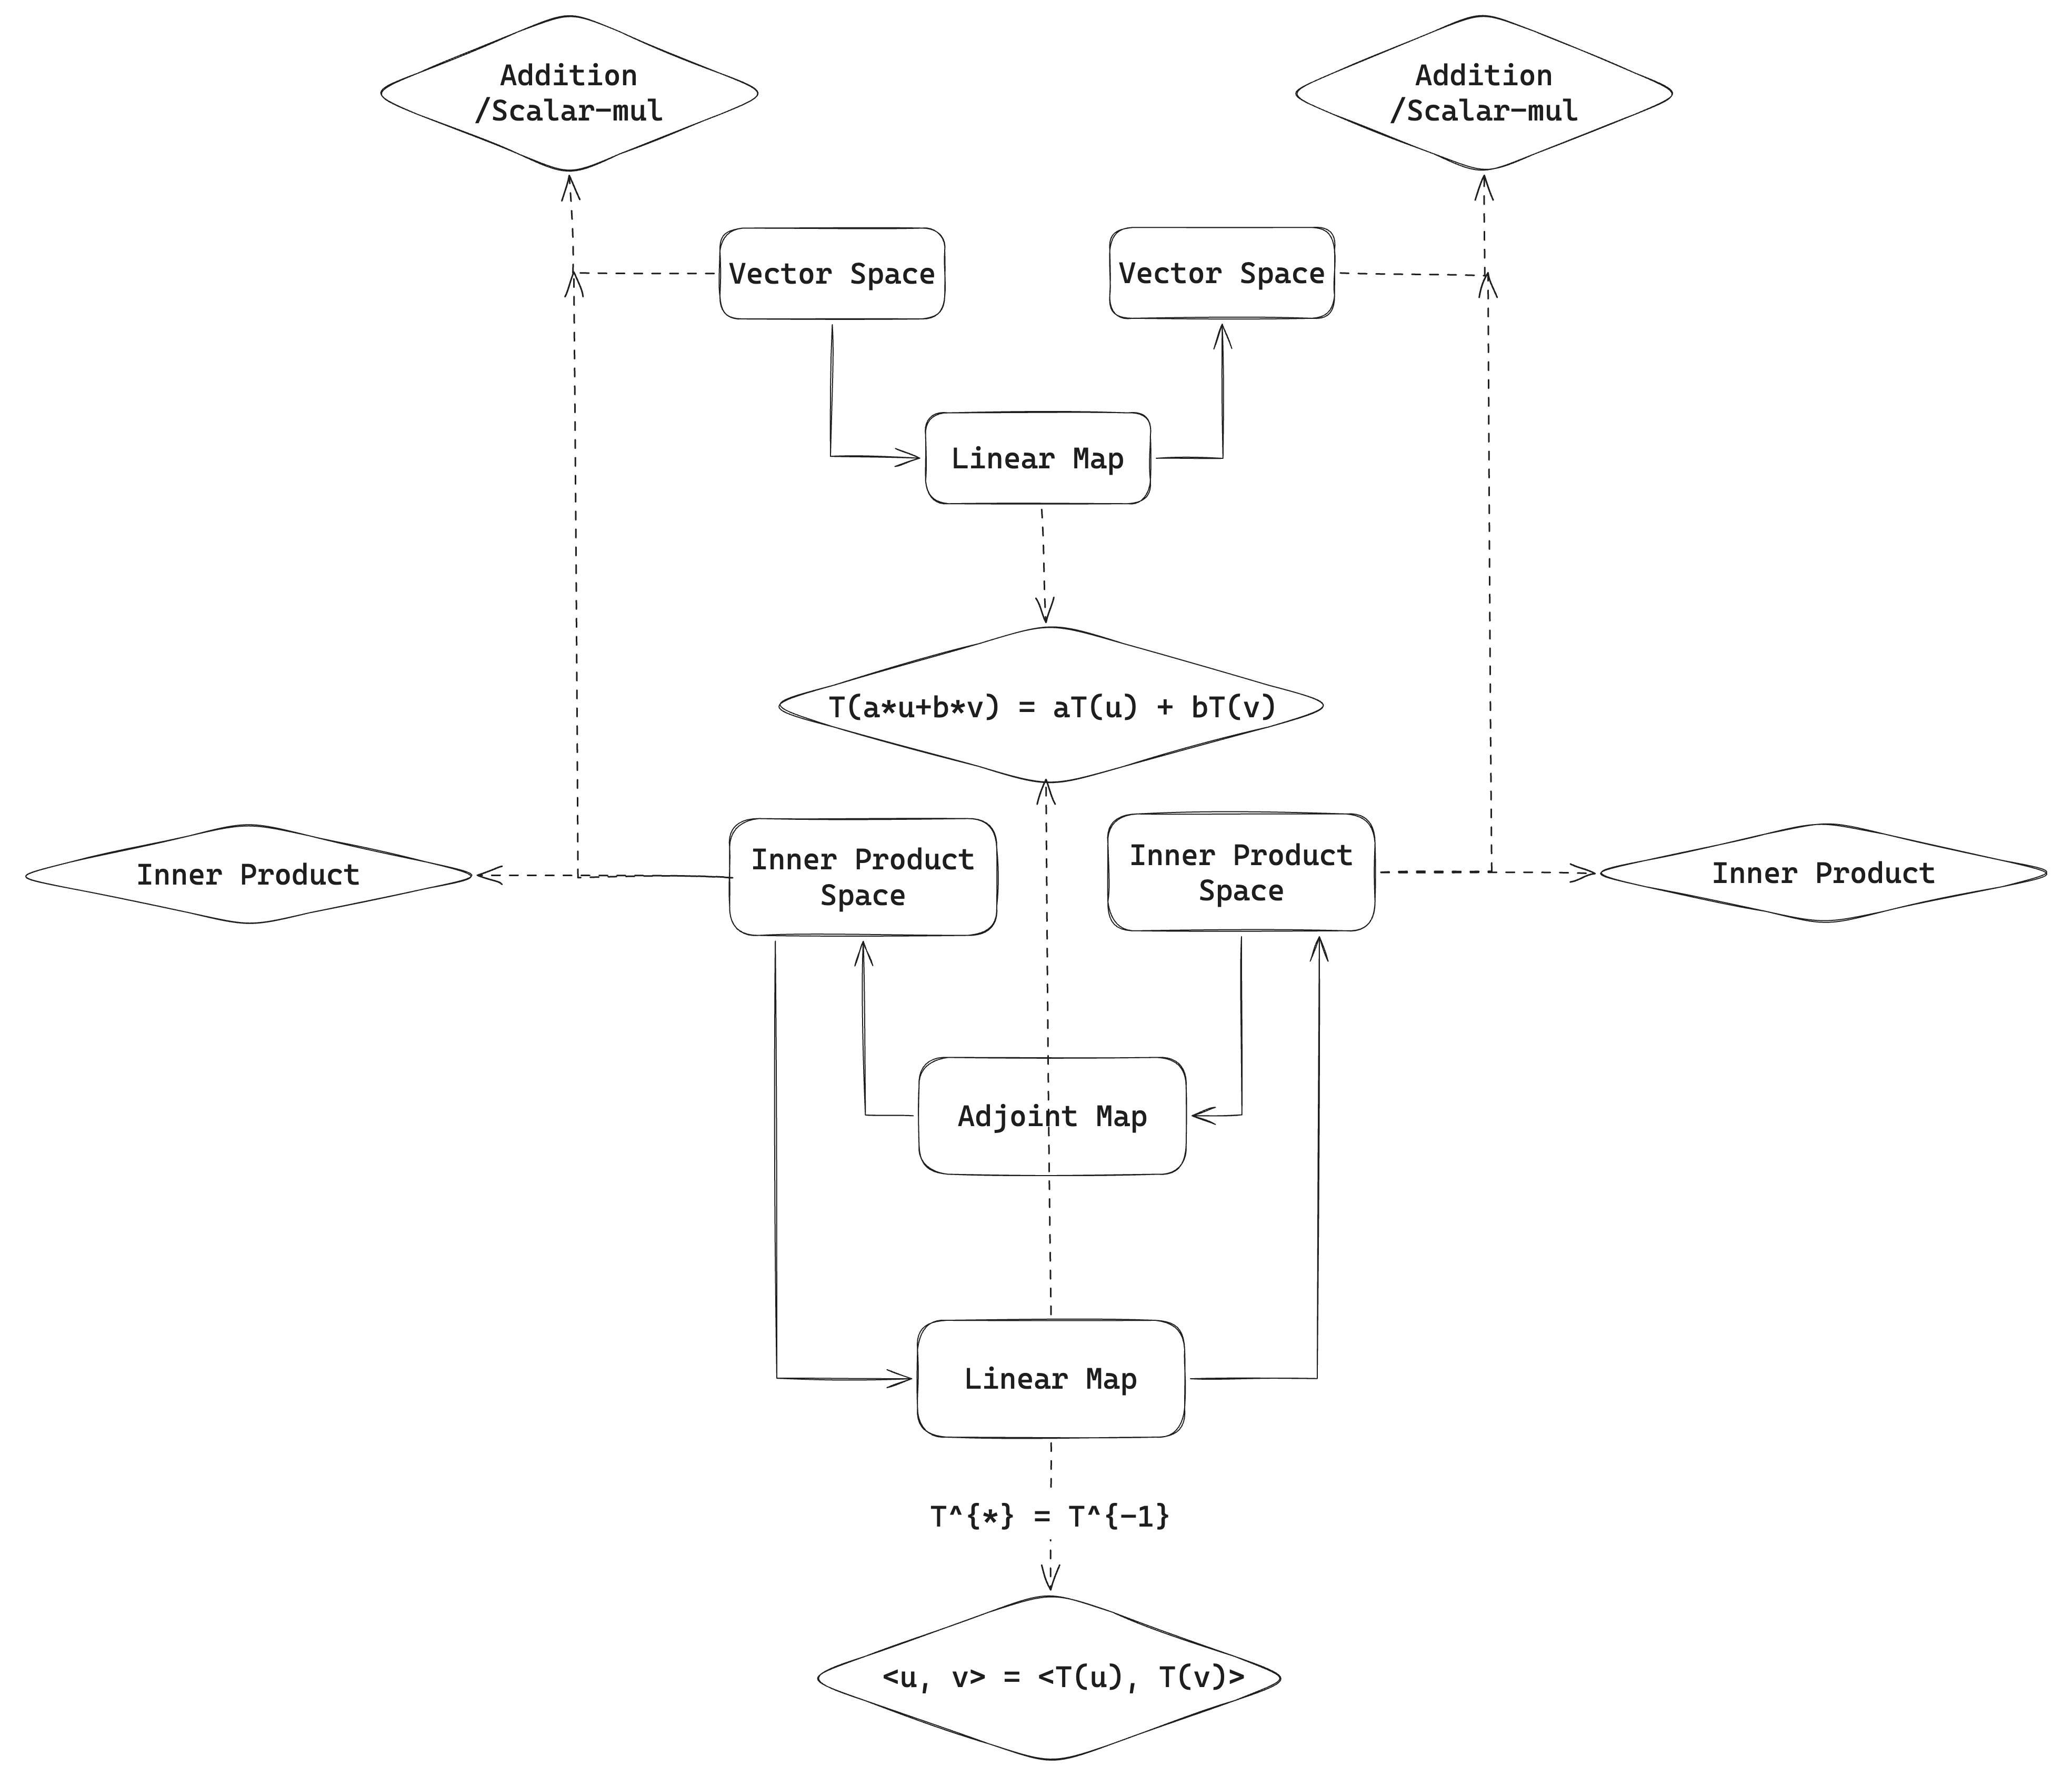
Before talking about adjoint operators, let's first explore the general adjoint linear map and its properties.
Linear Map of Inner Product Spaces

As we know, linear map is a homomorphism between vector spaces, preserving the algebraic operations of vector addition and scalar multiplication, we call this property as linearity. That is, there is one-to-one correspondence between the elements in the domain and the elements in the codomain, i.e.,

au+bv↦aT(u)+bT(v)for all v,u∈V and a,b∈F.

Inner product space is a special vector space which has an extra operation beyond vector addition and scalar multiplication, namely the inner product, that allows us to measure angles and lengths of vectors geometrically. But, inner product operation is not closure, it maps a pair of vectors to a scalar in the underlying field. So in general, we cannot expect the inner product operation to be preserved by linear maps. Furthermore, there is an equivalence between the inner product of two vectors in domain and the inner product of their images in the codomain under the linear map when the adjoint map is just the reversed of the linear map. That is,

⟨T(u),T(v)⟩=⟨u,T∗∘T(v)⟩=⟨u,v⟩ if T∗=T−1.

Adjoint Linear Map ​

Definition 7.1 - Adjoint Function

Suppose V is a finite-dimensional inner product space and T∈L(V,W). The adjoint function of T, denoted by T∗:W→V such that

⟨Tv,w⟩=⟨v,T∗w⟩for all v∈V,w∈W.

NOTE

The left-hand side of the equation is a inner product in W, and the right-hand side is the innner product in V. It seems like they have the same value in underline field. But how to make it happen, or how the adjoint operator T∗ is computed anyway?

Comuting the adjoint operator :

  1. Fix u∈V,x∈W, define T∈L(V,W) by T(v)=⟨v,u⟩x for all v∈V.

  2. Then

    ⟨Tv,w⟩=⟨⟨v,u⟩x,w⟩=⟨v,u⟩⟨x,w⟩=⟨v,⟨x,w⟩u⟩.

    Hence, the adjoint operator T∗∈L(W,V) is given by T∗(w)=⟨x,w⟩u for all w∈W.


Lemma 7.1 - Adjoint Function as a Linear Map

If T∈L(V,W), then the adjoint function T∗∈L(W,V) is also a linear map.

Proof

To show function T∗ is a linear map, we need to check its linearity property, i.e.,

(a) T∗(w1+w2)=T∗(w1)+T∗(w2).(b) T∗(λw)=λ⋅T∗(w)

Regarding (a), let v∈V, apply a inner product on the left-hand sides with v, we get

⟨T∗(w1+w2),v⟩=⟨w1+w2,Tv⟩=⟨w1,Tv⟩+⟨w2,Tv⟩=⟨T∗(w1),v⟩+⟨T∗(w2),v⟩=⟨T∗(w1)+T∗(w2),v⟩.

Hence, T∗(w1+w2)=T∗(w1)+T∗(w2), completing the proof of (a).

Regarding (b), similarly, let v∈V, apply a inner product on the left-hand side with v, we get

⟨T∗(λw),v⟩=⟨λw,Tv⟩=λ⟨w,Tv⟩=λ⟨T∗(w),v⟩=⟨λ⋅T∗(w),v⟩.

Hence, T∗(λw)=λ⋅T∗(w), completing the proof of (b).


Lemma 7.2 - Properties of the Adjoint Linear Map

Suppose T∈L(V,W). Then

  1. (S+T)∗=S∗+T∗ for all S∈L(V,W).
  2. (λT)∗=λ―T∗ for all λ∈F.
  3. (T∗)∗=T.
  4. (ST)∗=T∗S∗ for all S∈L(W,U) (here U is another finite-dimensional inner product space over the same field F).
  5. I∗=I where I is the identity operator on V.
  6. if T is invertible, then T∗ is also invertible and (T∗)−1=(T−1)∗.
Proof

The proofs of these properties follow directly from the definition of the adjoint operator and the linearity of the inner product.

  1. For all v∈V and w∈W, we have

    ⟨(S+T)∗w,v⟩=⟨w,(S+T)v⟩=⟨w,Sv⟩+⟨w,Tv⟩=⟨S∗w,v⟩+⟨T∗w,v⟩=⟨(S∗+T∗)w,v⟩.

    Hence, (S+T)∗=S∗+T∗.

  2. For all v∈V and w∈W, we have

    ⟨(λT)∗w,v⟩=⟨w,(λT)v⟩=⟨w,λTv⟩=λ―⟨w,Tv⟩=λ―⟨T∗w,v⟩=⟨λ―T∗w,v⟩.

    Hence, (λT)∗=λ―T∗.

  3. For all v∈V and w∈W, we have

    ⟨(T∗)∗v,w⟩=⟨v,T∗w⟩=⟨Tv,w⟩.

    Hence, (T∗)∗=T.

  4. For all v∈V and u∈U, we have

    ⟨(ST)∗u,v⟩=⟨u,STv⟩=⟨u,S(Tv)⟩=⟨S∗u,Tv⟩=⟨T∗S∗u,v⟩.

    Hence, (ST)∗=T∗S∗.

  5. For all v,w∈V, we have

    ⟨I∗v,w⟩=⟨v,Iw⟩=⟨v,w⟩.

    Hence, I∗=I.

  6. Since T is invertible, we have T−1T=I. Applying the adjoint operator to both sides, by (4) and (5), we get

    (T−1T)∗=I∗⟹(T∗)(T−1)∗=I⟹(T∗)−1=(T−1)∗.

Lemma 7.3 - Null Space and Range of Adjoint Linear Map

Suppose T∈L(V,W). Then

  1. null(T∗)=range(T)⊥.
  2. range(T∗)=null(T)⊥.
  3. null(T)=range(T∗)⊥.
  4. range(T)=null(T∗)⊥.
Proof

Regarding (1), let w∈W, by the definition 6.7 of orthogonal complement, we have :

w∈null(T∗)⟺T∗(w)=0⟺⟨T∗w,v⟩=0∀v∈V⟺⟨w,Tv⟩=0∀v∈V⟺w∈range(T)⊥

thus null(T∗)=range(T)⊥.

Replacing T with T∗ on (4), by property (3) in lemma 7.2, we get (2).

Replacing T with T∗ on (1), by property (3) in lemma 7.2, we get (3).

Applying orthogonal complement on both side of (1), we get (4).


Definition 7.2 - Conjugate Transpose (Adjoint)

The conjugate transpose of a m×n matrix A is the n×m matrix A∗ obtained by taking the transpose of A and then taking the complex conjugate of each entry. That is,

(A∗)j,k=Ak,j―

NOTE

As we know, a linear map T can be represented by a matrix A, so is there any relationship between the adjoint of a matrix A∗ and the adjoint T∗ of the corresponding linear map T?


Lemma 7.4 - Adjoint Matrix and Adjoint Linear Map

Let T∈L(V,W). Suppose e1,...,en is an orthonormal basis of V and f1,...,fm is an orthonormal basis of W. Then M(T∗,(f1,...,fm),(e1,...,en)) is the conjugate transpose of M(T,(e1,...,en),(f1,...,fm)). In other words,

M(T∗)=(M(T))∗
Proof

By the definition of matrix of linear map, the k-th column of M(T∗) is given by the coordinates of T∗(fk) with respect to the basis (e1,...,en). That is,

T∗(fk)=c1,k⋅e1+...+cn,k⋅en∈W

where cj,k is the (j,k)-th entry of the matrix M(T∗).


By the definition of orthonormal basis, vector T∗(fk) can be uniquely expressed as a linear combination of the orthonormalbasis (e1,...,en):

T∗(fk)=∑j=1n⟨T∗(fk),ej⟩ej

which implies that the (j,k)-th entry of M(T∗) is given by

cj,k=⟨T∗(fk),ej⟩

By the definition of adjoint of linear map, we have

⟨T∗(fk),ej⟩=⟨fk,T(ej)⟩=fk⋅T(ej)―=fk――⋅T(ej)―=⟨fk―,T(ej)―⟩―=⟨T(ej),fk⟩―

where ⟨T(ej),fk⟩ is just the (k,j)-th entry of the matrix M(T).


Therefore, the (j,k)-th entry of M(T∗) is the complex conjugate of the (k,j)-th entry of M(T), which shows that M(T∗) is the conjugate transpose of M(T).


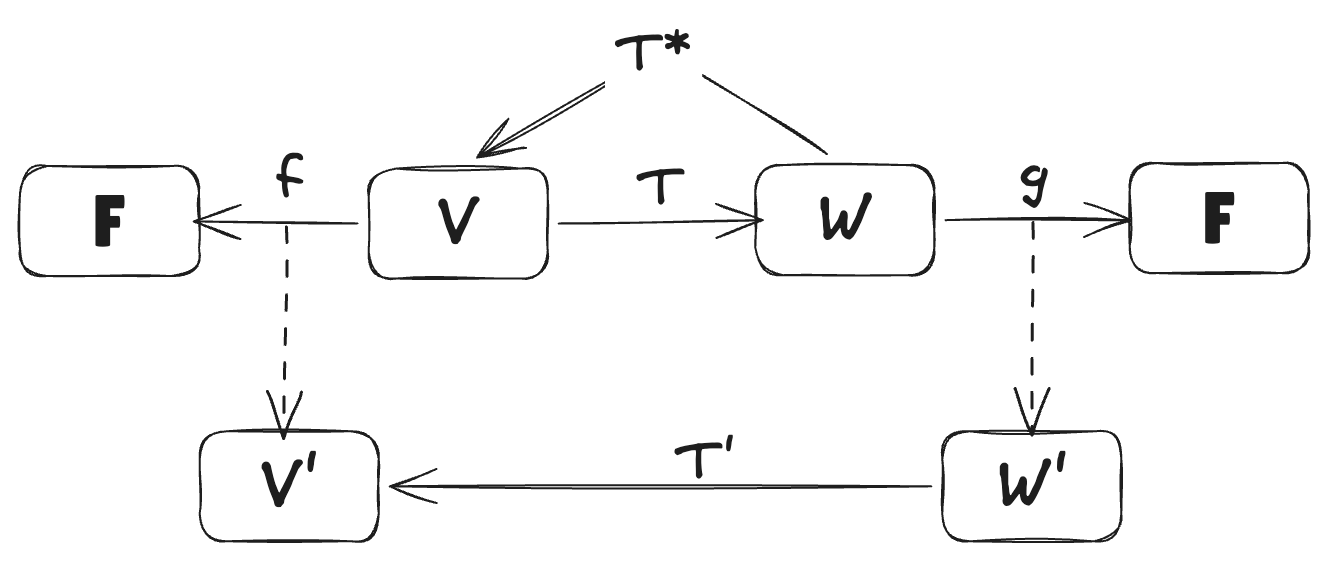
Adjoint Map VS Dual Map

As we know, for inner product spaces, there is a one-to-one map (i.e., an equivalence ≅) between vector space V and its dual space V′. More specially, every vector v∈V corresponds a unique linear function fv∈V′ that maps any vector u∈V to the inner product ⟨v,u⟩, i.e.,

v∈V↦fv∈V′:u↦⟨v,u⟩,∀u∈V

The collection of the linear functions fv forms the dual space V′, so as dual space W′. The dual map between these two dual spaces is defined by

(T′)g=g∘T∈V′ for any g∈W′

In contrast, the adjoint map T∗ of linear map T is defined by

T∗(w)=⟨w,u⟩⋅x∈V for some u∈W,x∈V, for all w∈W

Even though the domain and codomain of the dual map T′ and the adjoint map T∗ are separately different, but they are related by the equivalences V≅V′ and W≅W′, these two maps share a similar relationship with the range and null space of the original map. Take the null space for example:

(range(T))0≅(range(T))⊥∥∥null(T′)≅null(T∗)

For the dual map, we have null(T′)=(range(T))0; for the adjoint map, we have null(T∗)=(range(T))⊥. Where the complement is defined as :

(range(T))⊥={v∈V∣⟨v,w⟩=0,∀w∈range(T)}

, and the annihilator (range(T))0 is defined as

(range(T))0={f∈V′∣f(w)=0,∀w∈range(T)}

Define f=fv:V→F by

fv(u)=⟨v,u⟩,∀u∈V

Thus (range(T))⊥ corresponds to the annihilator (range(T))0 under the equivalence V≅V′, furthermore, null(T∗) corresponds to null(T′) under the same equivalence. This also applies to the range of the maps. Therefore, there is a one-to-one correspondence between the structures of the dual map and the adjoint map.

adjoint dual map

Self-adjoint Operators ​

Self-adjoint is a special case of adjoint operators where the operator is equal to its own adjoint.

Definition 7.3 self-adjoint operator

An operator T:V→V on an inner product space V is called self-adjoint if T=T∗, i.e.,

⟨T(v),u⟩=⟨v,T(u)⟩,∀v,u∈V

By lemma 7.4, we can also check :

M(T,(e1,...,en))=M(T,(e1,...,en))∗

Lemma 7.5 - Eigenvalues of Self-adjoint Operators

If F=C, then every eigenvalue of a self-adjoint operator is real.

Proof

Let λ be an eigenvalue of a self-adjoint operator T with corresponding eigenvector v≠0. Then

λ∥v∥2=⟨λv,v⟩=⟨T(v),v⟩=⟨v,T(v)⟩=⟨v,λv⟩=λ―∥v∥2

Since v≠0, we have ∥v∥2≠0, and thus λ=λ―, which means λ is real.


Normal Operators ​

Definition 7.4 - Normal Operator

An operator T:V→V on an inner product space V is called normal if TT∗=T∗T.

NOTE

If an operator T is normal, it does not necessarily have to be self-adjoint, but every self-adjoint operator is normal.


Lemma 7.6 - Criteria of Normal Operators

An operator T:V→V on an inner product space V is normal if and only if ∥T(v)∥=∥T∗(v)∥ for all v∈V.

Proof

Let T be normal. Then TT∗=T∗T. For any v∈V, we have

∥T(v)∥2=⟨T(v),T(v)⟩=⟨T∗T(v),v⟩=⟨TT∗(v),v⟩=⟨T∗(v),T∗(v)⟩=∥T∗(v)∥2.

Conversely, if ∥T(v)∥=∥T∗(v)∥ for all v∈V, then

⟨(TT∗−T∗T)(v),v⟩=∥T∗(v)∥2−∥T(v)∥2=0,∀v∈V.

Since ⟨(TT∗−T∗T)(v),v⟩=0 for all v∈V, it follows that TT∗−T∗T=0, i.e., TT∗=T∗T.


Multilinear Algebra and Determinants ​

Bilinear Forms and Quadratic Forms ​

This section will mainly introduce two sub-types of bilinear forms : symmetric bilinear forms and alternating bilinear forms. More interestingly, every bilinear form space can be decomposed into a direct sum of its symmetric and alternating subspaces. That means for any bilinear form β∈V(2), it is either symmetric or alternating.

Bilinear Forms ​

Definition 9.1 - Bilinear Form

A bilinear form on V is a function β:V×V→F such that

v↦β(v,u), and v↦β(u,v)∀u∈V

are both linear functions on V.

NOTE

By definition, bilinear form β itself is not necessarily a linear function (or linear map), maybe it works for some special structure of β, but its partial function β(⋅,u) or β(u,⋅) that maps a vector v∈V to β(v,u) or β(u,v) is a linear function.


If let β=⟨⋅,⋅⟩ be the inner product on inner product space V, then

  • if F=R, then β is a bilinear form.
  • if F=C, then β is not a bilinear form. Since β(u,λv)=⟨u,λv⟩=λ―⟨u,v⟩=λ―β(u,v), it is not linear in the second argument.

Surely, bilinear form can be any other functions beyond the inner product. For example, Suppose two dual elements from dual space φ,τ∈V′. Then the function β:V×V→F defined by β(u,v)=φ(u)τ(v) is a bilinear form.


Definition 9.2 - Vector Space of Bilinear Forms

The set of all bilinear forms on a vector space V over a field F forms a vector space V(2) over F with the operations of pointwise addition and scalar multiplication, i.e., for β1,β2∈V(2) and λ∈F,

(β1+β2)(u,v)=β1(u,v)+β2(u,v),(λβ1)(u,v)=λβ1(u,v),∀u,v∈V.

Definition 9.3 - Matrix of a Bilinear Form

Suppose β∈V(2) is a bilinear form on an n-dimensional vector space V with a basis {e1,…,en}. The matrix of β with respect to this basis is the n×n matrix M(β) defined by

M(β,(e1,…,en))i,j=β(ei,ej),1≤i,j≤n.

You may wonder why the biliear form also has matrix representation just like any other linear maps? This owes to the fact that partial function of a bilinear form β(u,⋅) or β(⋅,v) is a linear map. That is,

β(x,y)=β(∑ixiei,∑jyjej)=∑i,jxiβ(ei,ej)yj=xTM(β)y

Thus algebraic operations on bilinear forms are reflected by vector-matrix-vector multiplication.


Lemma 9.1 - Isomorphism between Bilinear Forms and Its Matrices

Suppose e1,...,en is a basis of V. Then the map β↦M(β) is a vector space isomorphism between the vector space of bilinear forms V(2) and the vector space of n×n matrices over F. Furthermore, dim⁡V(2)=(dim⁡V)2.

Proof

The map β↦M(β) is clearly linear. To see that it is bijective, note that given any n×n matrix A=[aij], we can define a bilinear form β by β(ei,ej)=aij and extending bilinearly. This shows that every matrix corresponds to a unique bilinear form, hence the map is an isomorphism.


Lemma 9.2 - Composition of Bilinear Form and Operator

Suppose β∈V(2) is a bilinear form on a vector space V and T:V→V is a linear operator. Define bilinear form α,ρ∈V(2) by

α(u,v)=β(u,T(v)),ρ(u,v)=β(T(u),v),∀u,v∈V.

Let e1,...,en be a basis of V. Then

M(α)=M(β)M(T),M(ρ)=M(T)tM(β)
Proof

By the definition of matrix of a bilinear form, we have :

M(α)i,j=α(ei,ej)=β(ei,T(ej))=β(ei,∑k=1nM(T)k,jek)=∑k=1nM(T)k,jβ(ei,ek)=∑k=1nM(T)k,jM(β)i,k=(M(β)M(T))i,j

The third equality follows from the definition of matrix of a operator, the fourth equality follows from the linearity of bilinear form in the second argument, and the fifth equality follows from the definition of matrix of a bilinear map.

The proof for M(ρ)=M(T)tM(β) is similar, using the linearity of the bilinear form in the first argument and the definition of the matrix of a linear operator.


NOTE

Generally, the matrix of a bilinear form of vector space V depends on : 1) the choice of the basis of V. 2) the bilinear form itself. Since the domain of bilinear map is tuple vectors from V×V, the basis of V×V is taken as the product of the bases of V on both arguments, but in default we only consider the same basis for both arguments. This is why we denote the matrix of bilinear form β on V as :

M(β,(e1,…,en))

in default. But similar with matrix of linear operator, if we want to consider different bases for the two arguments of the bilinear form, we would need to specify both bases explicitly.

Lemma 9.3 - Change of Basis for Bilinear Form

Suppose β∈V(2) is a bilinear form on a vector space V. Let e1,...,en and f1,...,fn be two bases of V. Let

A=M(β,(e1,...,en)),B=M(β,(f1,...,fn))

and C=M(Id,(e1,...,en),(f1,...,fn)) be the change of basis matrix from the basis (e1,...,en) to the basis (f1,...,fn). Then we have

B=CtAC.

Symmetric Bilinear Forms ​

Definition 9.4 - Alternating Bilinear Form

A bilinear form α∈V(2) on a vector space V is called alternating if for all v∈V, we have

α(v,v)=0.

Lemma 9.4 - Characterization of Alternating Bilinear Forms

A bilinear form α∈V(2) on a vector space V is alternating if and only if it is skew-symmetric, i.e., for all u,v∈V, we have

α(u,v)=−α(v,u).

Definition 9.5 - Symmetric Bilinear Form

A bilinear form ρ∈V(2) on a vector space V is called symmetric if for all u,v∈V, we have

ρ(u,v)=ρ(v,u).

Lemma 9.5 - Symmetric Bilinear Forms or Alternating Bilinear Forms

The sets Vsym(2) and Valt(2) of symmetric and alternating bilinear forms on a vector space V are subspaces of V(2). Furthermore,

V(2)=Vsym(2)⊕Valt(2).
Proof

Proof logic :

  1. We need to show Vsym(2) is a subspace of V(2). This involves checking that it is closed under addition and scalar multiplication, and that it contains the zero bilinear form.

  2. The same argument applies to Valt(2), showing that it is also a subspace of V(2).

  3. In order to show that V(2)=Vsym(2)⊕Valt(2), two steps involved :

    a. Show V(2)=Vsym(2)+Valt(2).

    b. Show Vsym(2)∩Valt(2)={0}.

We omit the detailed proof here..


Lemma 9.6 - Diagonalization of Symmetric Bilinear Forms

Suppose ρ∈V(2). Then

  1. ρ is a symmetric bilinear form on V.
  2. M(ρ,(e1,...,en)) is a symmetric matrix for every basis e1,...,en of V.
  3. M(ρ,(e1,...,en)) is a diagonal matrix for some basis e1,...,en of V.

are equivalent.

Proof

By definition 9.3, any evaluation of a bilinear form can be represented as vector-matrix-vector multiplication:

β(u,v)=uTAv

Since ρ is symmetric, β(u,v)=β(v,u), there must exists a basis e1,...,en of V with respect to which the matrix representation of β is symmetric, i.e.,

uTAv=vTAu⟺A=AT.

Completing the proof of (2). Diagonal matrix is just a special case of symmetric matrix, which means there also exists some basis such that the matrix of this symmetric bilinear form is a diagonal matrix. Completing the proof of (3).


Quadratic Forms ​

Consider the function of bilinear form β∈V(2),

β:V×V→F,(u,v)↦β(u,v).

More specially, β(v,v) defines a quadratic form associated with the bilinear form β.


Definition 9.6 - Quadratic Form

For β a bilinear form on V, define a function qβ:V→F by

qβ(v)=β(v,v),∀v∈V.

This function qβ is called the quadratic form associated with the bilinear form β.


Suppose n is positive integer and q is a function from Fn to F. Then q is quadratic form on Fn if there exists a matrix of bilinear form A∈Fn×n such that

q(x1,...,xn)=∑i,jAi,jxixj∀(x1,..,xn)∈Fn.

Lemma 9.7 - Characterization of Quadratic Forms

Suppose q is a quadratic form on vector space V. Then it implies :

  1. There exists a unique symmetric bilinear form ρ on Fn such that q=qρ.
  2. q(λv)=λ2q(v),∀λ∈F,∀v∈Fn., and the function(u,w)↦q(u+w)−q(u)−q(w)is a symmetric bilinear form on V.
  3. q(2v)=4q(v),∀v∈V. and the function(u,w)↦q(u+w)−q(u)−q(w)is a symmetric bilinear form on V.
Proof

For (1), q is a quadratic form on V implies there exists a bilinear form β such that

q(v)=β(v,v),∀v∈V.

By lemma 9.5, β can be decomposed into a symmetric bilinear form ρ and an alternating bilinear form α, i.e.,

β=ρ+α,∀u,v∈V.

Thus we have q=qβ=qρ+qα=qρ. In order to show the uniqueness of ρ, we suppose ρ′ is another symmetric bilinear form such that q=qρ′. Then we have

qρ=qρ′⟹qρ−ρ′=0.

Since ρ−ρ′ is symmetric, it follows that ρ−ρ′=0, i.e., ρ=ρ′. Hence, the symmetric bilinear form ρ is unique.


For (2), suppose q=qβ where β is a bilinear form on V. Then :

q(λv)=β(λv,λv)=λ2β(v,v)=λ2q(v),∀λ∈F,∀v∈V.

Next, we show that the function

(u,w)↦q(u+w)−q(u)−q(w)

is a symmetric bilinear form on V. By (1), we have q=qρ where ρ is the unique symmetric bilinear form associated with q, we have :

q(u+w)−q(u)−q(w)=ρ(u+w,u+w)−ρ(u,u)−ρ(w,w)=ρ(u,w)+ρ(w,u)=2ρ(u,w),∀u,w∈V.

Hence, the function above is a symmetric bilinear form 2ρ on V.


For (3), the proof is similar to (2), we omit the details.


Lemma 9.8 - Diagonalization of Quadratic Forms

Suppose q is a quadratic form on V. Then

  1. There exists a basis e1,...,en of V and λ1,...,λn∈F such thatq(∑i=1nxiei)=∑i=1nλixi2,∀(x1,...,xn)∈Fn.
  2. If F=R and V is an inner product space, then the basis e1,...,en can be chosen to be orthonormal with respect to the inner product.
Proof

Suppose β∈V(2) is a symmetric bilinear form associated with the quadratic form q, i.e., qβ(v)=β(v,v) for all v∈V. Furthermore, qβ must be symmetric. By Lemma 9.6, there exists a basis e1,...,en of V such that the matrix representation of β with respect to this basis is diagonal:

β(∑i=1nxiei,∑j=1nxjej)=∑i=1nλixi2,∀(x1,...,xn)∈Fn,

where λi are the diagonal entries of the matrix representation of β with respect to the basis e1,...,en. Therefore,

q(∑i=1nxiei)=∑i=1nλixi2,∀(x1,...,xn)∈Fn.

Completing the proof of (1).


Alternating Multilinear Forms ​


Determinants ​


Tensor Products ​


Published with GitHub Pages.